
Category: AI/ML
-
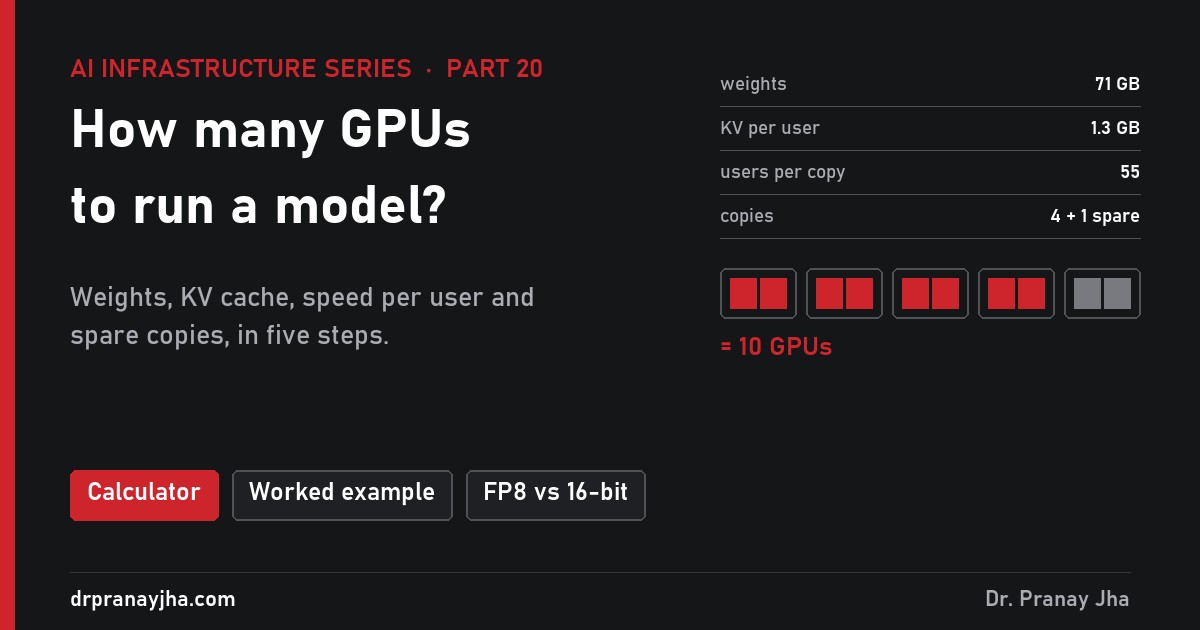
How many GPUs do you need to run a model?
A five-step method to size GPUs for serving an LLM: weights, KV cache per user, GPUs per copy, users per copy from memory and speed limits, and copies plus spares. With a worked Llama 3.1 70B example, a table of common setups and what the method leaves out.
-
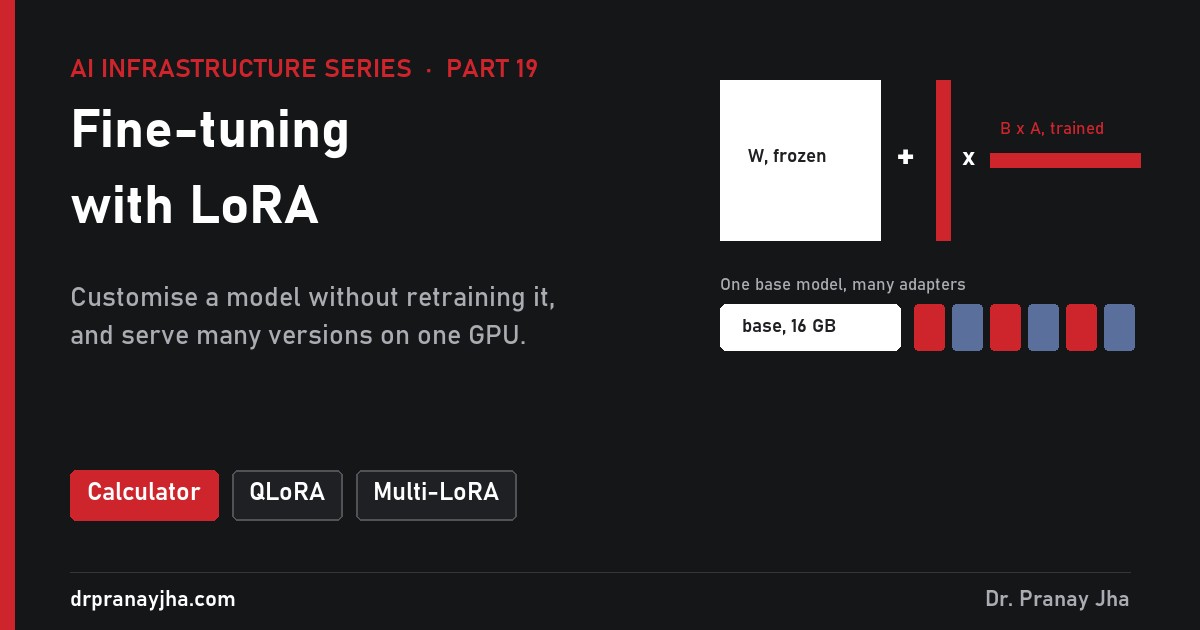
Fine-tuning with LoRA: how to customise a model without retraining it
How LoRA customises a model by training a small adapter next to frozen weights: when fine-tuning helps, how low-rank adapters work, GPU memory for full fine-tuning vs LoRA vs QLoRA, how to train an adapter, and serving many adapters on one base model with vLLM.
-
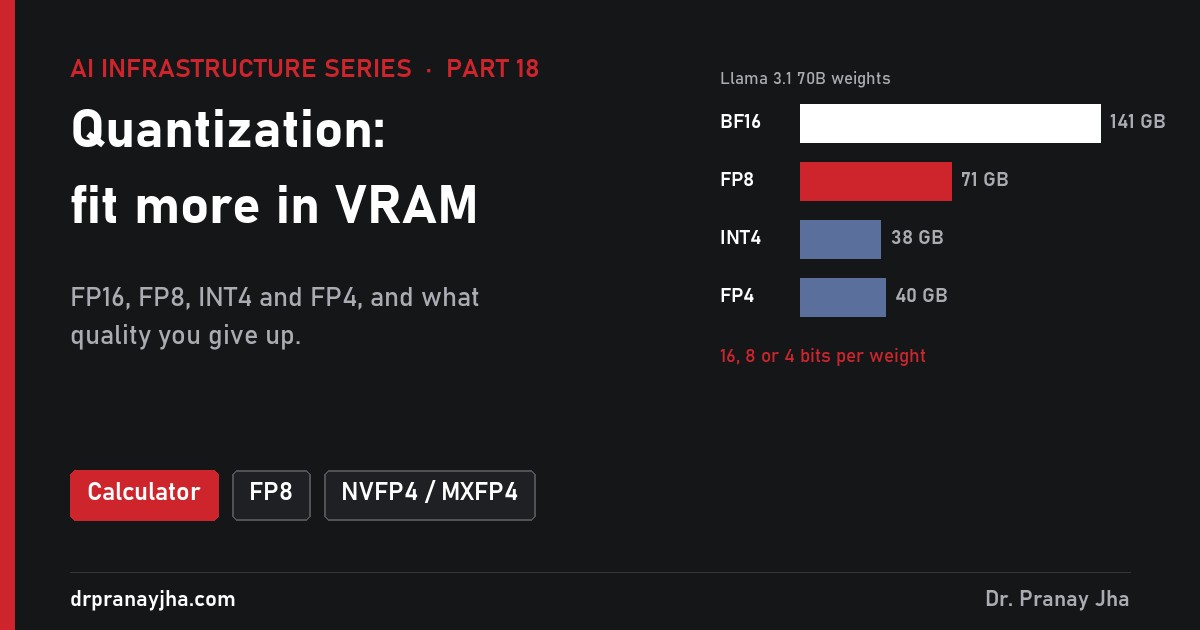
Quantization: how to fit a bigger model in less VRAM
How quantization shrinks LLM weights from 16-bit to 8-bit and 4-bit: the formula, why it speeds up decode, FP8, INT8, INT4, NVFP4 and MXFP4 explained, how much quality you lose, how to quantize a model and how to choose a format for your GPUs.
-
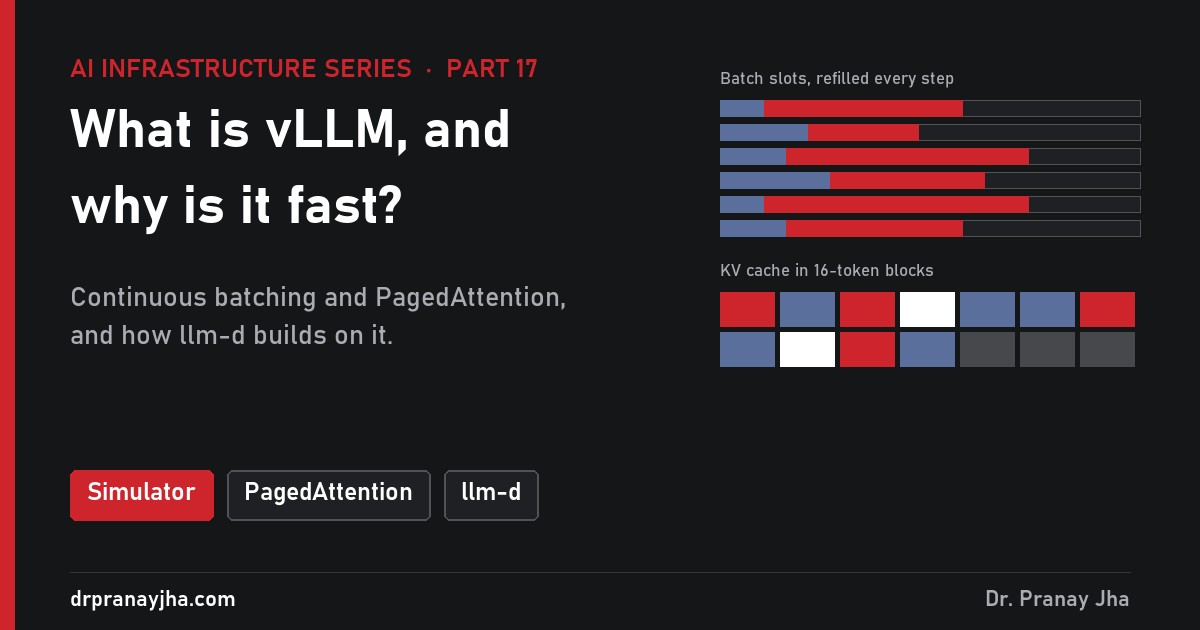
What is vLLM, and why is it fast?
vLLM explained for infrastructure teams: continuous batching, PagedAttention and the KV cache, prefix caching and other speed-ups, the settings that matter, and how llm-d adds cache-aware routing and split prefill and decode on top of vLLM.
-
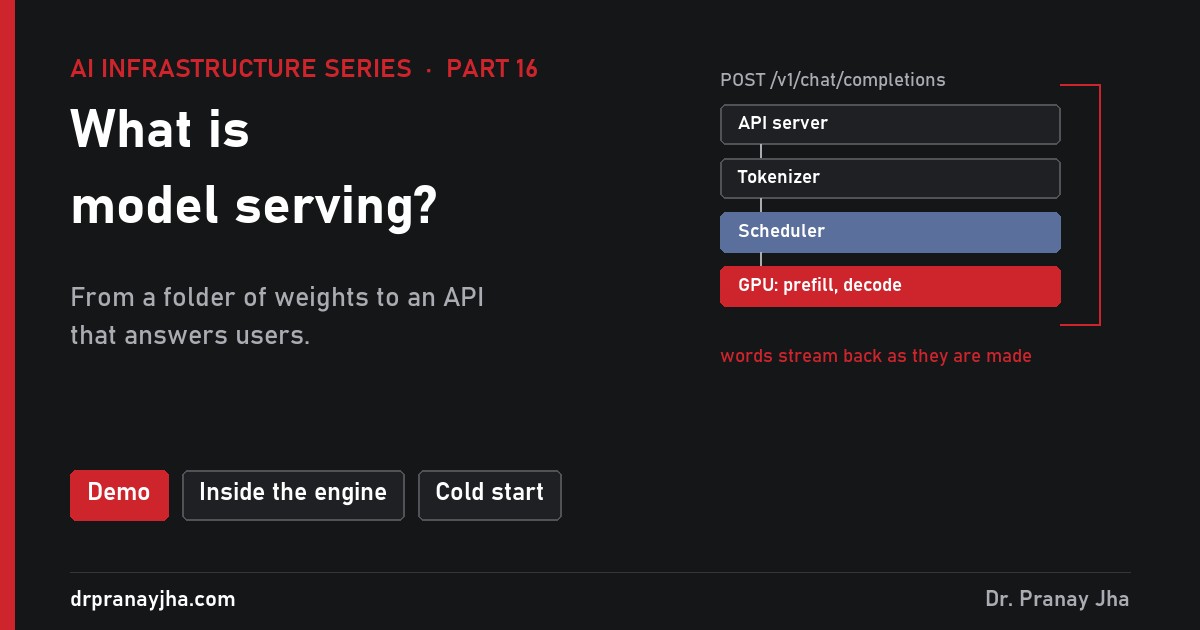
What is model serving? From a model file to an API
What turns a folder of model weights into an API: what is in a model file, what a serving engine does (API, tokenizer, scheduler, GPU workers, streaming), the main engines, what happens when a server starts, and what else production serving needs.
-
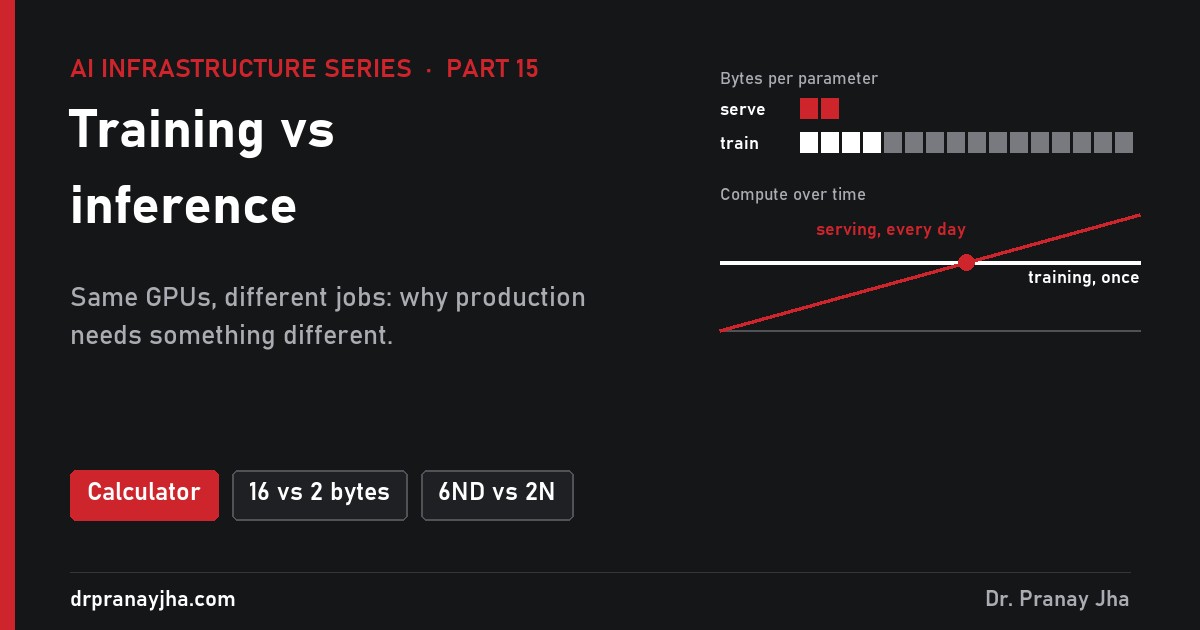
Training vs inference: why production needs something different
Training builds a model once; inference runs it every day. How the two differ in memory (16 bytes vs 2 bytes per parameter), compute, network and operations, when serving overtakes training, and what production inference needs.
-
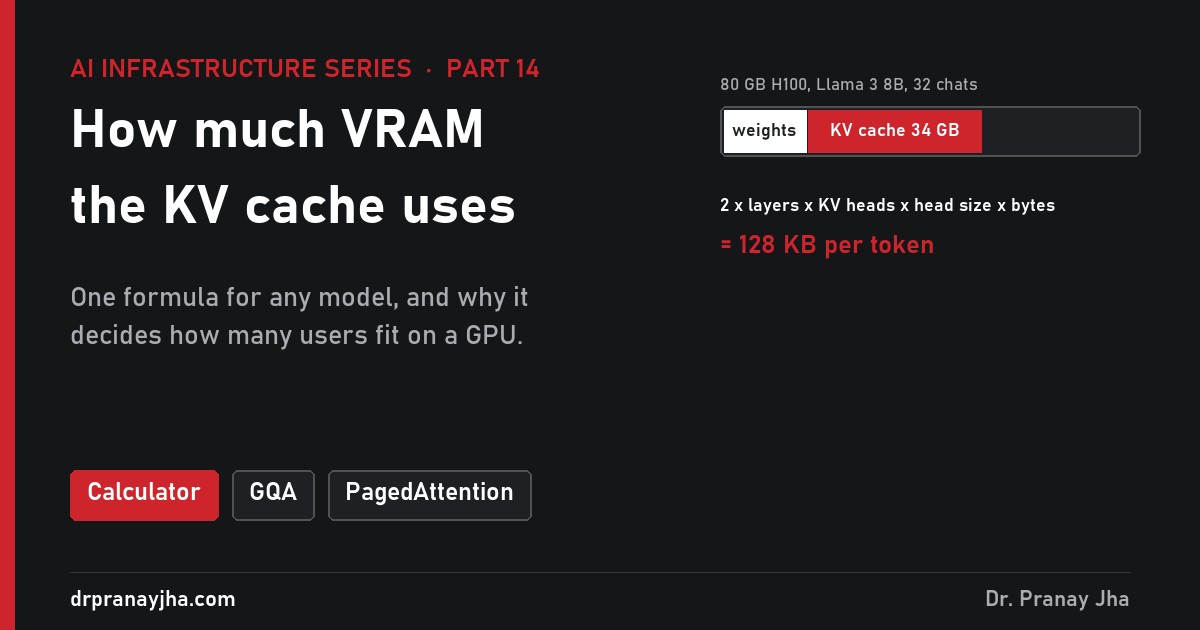
How much VRAM does the KV cache use?
Calculate the KV cache for any model: the formula, real numbers for Llama 3 8B to 405B and DeepSeek-V3, why grouped-query and latent attention make it smaller, how it limits users and context, and how paged memory fits more users.
-
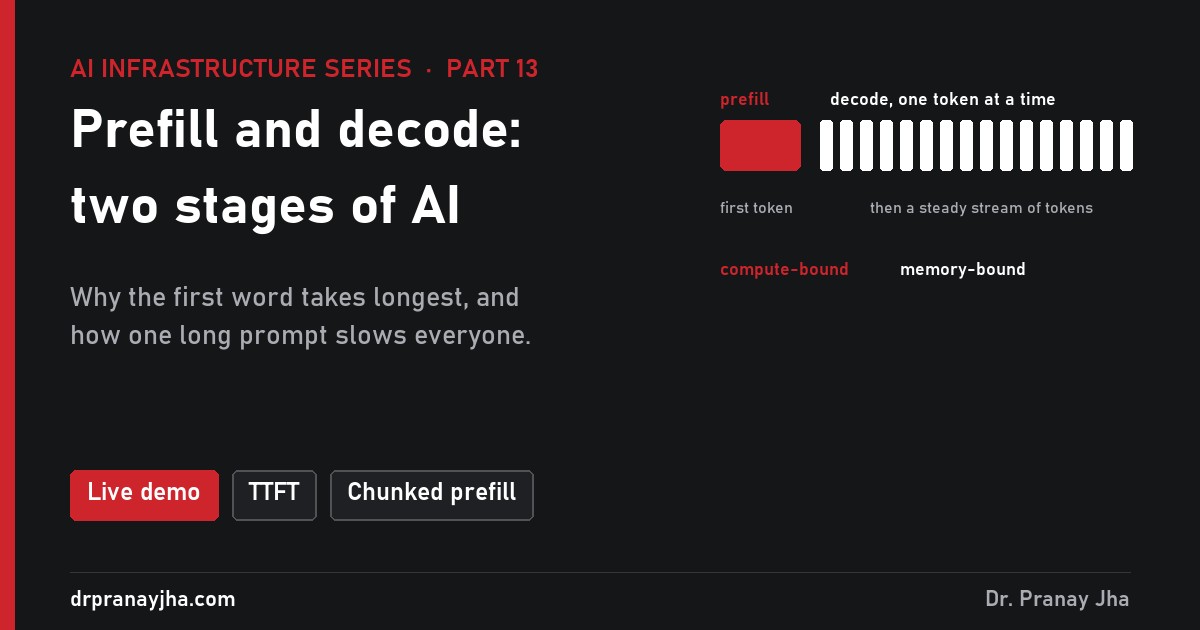
Prefill and decode: the two stages of every answer
Every LLM answer has two stages: prefill reads the prompt and sets the wait for the first word; decode writes the answer and sets the time per word. Why they stress GPUs differently, why long prompts stall other users, and how to speed up each.
-
What is a Mixture of Experts model, and why does it need less GPU power?
DeepSeek-V3 has 671 billion parameters but uses 37 billion per token. How Mixture of Experts models work, what they save and what they do not, why batching wakes almost every expert, and what MoE needs from GPUs and NVLink.
-
What happens inside a transformer when you ask a question?
Follow one question through a Llama-style 8B model: tokens, embeddings, attention with queries, keys and values, the MLP blocks, 32 layers and the final scores, plus where the 8 billion parameters actually sit.
-
Frontier models vs open models: which can you run yourself?
Frontier models through an API, or open models on your own GPUs? Open weights vs open source, how big open models really are and what each size needs, how they compare, and when self-hosting actually pays.
-
What is an LLM, and how does it work?
A large language model predicts the next piece of text, over and over. Tokens, parameters and layers, how it picks each word with temperature and top-p, how it learns, and what decides the hardware it needs.
Architect’s Toolkit
PJ’s Tools
- Infra 360 Hub – All Series
- VCF Exam Practice Labs
- VCF 9 Interactive Walkthroughs
- VCF Design Cheatsheet
- VCF Upgrade Planner
- VCF 9 Series Hub
- VCF Deployment Hub
- AI Stack Hub
- AI Infra Sizing & Cost Calculator
- LLM & RAG Cost Calculator
- DrJhaGPT – Ask Pranay
VMware Cloud Foundation
- VCF Documentation
- VCF 9 Planning & Preparation Workbook
- VCF Bill of Materials (BoM)
- VMware Compatibility Guide
- VMware Interoperability Matrix
- VMware Configuration Maximums
- VMware Ports & Protocols
- VMware Hands-on Labs
- RVTools Download
Nutanix
AI & Cloud-Native Platform
- NVIDIA Build (Model Catalog)
- NVIDIA AI Enterprise Reference Architecture
- NVIDIA NIM Performance Benchmarking
- NVIDIA NGC Catalog
- NeMo Microservices Helm Chart
- Helm Charts Repository
- Hugging Face Models
Architecture & Design
About the Author

Dr Pranay Jha
Dr. Pranay Jha is a Cloud and AI Consultant with 18+ years of experience in hybrid cloud, virtualization, and enterprise infrastructure transformation. He specializes in VMware technologies, multi-cloud strategy, and Generative AI solutions. He holds a PhD in Computer Applications with research focused on Cloud and AI, has published multiple research papers, and has been a VMware vExpert since 2016 and a VMUG Community Leader.
You May Have Missed






 DrJha